After the 2016 election, progressive activists in the United States grew very serious about digital security training to protect themselves from surveillance. Prior to that, there had been a fair bit of money for digital security training for journalists and human rights groups abroad — much of it, ironically, provided by the U.S. government. Many digital security guides had been written, and now there was more pressure, and some funding, to write even more of them.
I was at EFF at the time, and we were a bit sceptical of the benefits of writing yet another guide. It wasn’t really clear how useful they were. A long how-to guide explaining how encryption works, which ended with a hurried installation tutorial on PGP: we’d all written some variant of it, but did anyone actually get through one? Did they trust what they’d learned enough to use it in practice? In the end, saying “Use strong passwords, Signal, and Tor” got you 75% of the way there — and the other 25% was near impossible to teach to anyone but the most dedicated.
But it was those dedicated few that fascinated me. They were usually interested in the theory behind encryption; they were comfortable installing new tools on their laptops or phones. They ended up doing tech support — of all kinds — for the rest of their community.
I felt this was a general pattern: every social group (including families) generally had one lynchpin techie, who reset their phones when they needed them, devirused their PCs, and advised them on what tech to buy and what software to use. These techies spread the Good Word About Firefox, and had nothing good to say about any printer, ever. Except maybe Brother, grudgingly.
I felt that maybe EFF could reach these folks — the benefit of being a key institution in the early geek years was that people who were culturally technological knew your name, and read your work. We wrote some basic guides on securing your devices for them to use, which I’m very happy to say are still being reviewed and maintained (top tip: if you write a security guide, be prepared to keep it updated forever lest it become worse than useless).
But we also wrote a partner website, Security Education Companion, which was a crash course, not on how to use encryption, but on how to teach it. Researching and writing this sometimes felt less like self-education, and more like self-analysis:
When giving a presentation, many people in the audience get flashbacks to school and start treating you very differently. They expect you to have all the answers. People who previously switched off entirely when you explained how awesome Linux is suddenly begin hanging onto your every word. They might even start taking notes.
Do not let this new power go to your head! It can get in the way of actually conveying useful information. It can also mess with your own instincts about how to best get a point across.
We knew that these people were like us — and like us, they were going to be extremely tempted to install Linux on everyone’s laptops. We had to steer them away from this, and get them to listen to their audience’s needs.
Even though I had a very strong idea of who these people were — and had the opportunity to hang out and plot with them across the world, from Thailand to Paraguay — I never really found a satisfactory name for us.
They knew the hardware and software well, but weren’t necessarily paid to use it. They managed it for their whole community, and they were rarely selling anything.
Who are they? Who are we?
How do we not know what we are?
This cropped up again as Farzaneh Badii and I have been plotting the strategy for Terminal Values, our new radical digital rights NGO. Really, if we’re trying to distil the point of view of anyone, it’s this community.
For a while, makers and builders became the popular usage in some crowds, but I think those too got trapped in a particular moment of history.
For the last ten years, I’ve generally used “technologists”, or if really pressed, “public interest technologists”. But I really don’t think this community has ever been as comfortably middle-class as that makes it sound. In fact, the closer anyone comes to coining a safe, careerist term, the more the subculture starts desperately swimming away from its own nomenclature.
I feel weird even as I try to capture the moment now: every “we’re like this” feels too narrow. And without a name, people have mostly got lost in a maze of other identities, some medicalising, some fun but maybe a bit politicising, picking a side in a wider cultural battle, rather than choosing a term with broader scope. Which means kids growing up now stumble on the names from the past, and wear them like an old band’s t-shirt that doesn’t fit them yet.
As our internal shorthand at Terminal Values, we’ve ended up calling them — us — “street techs”. Farzaneh and I came up with this while pondering how our relationship to tech and the tech industry hints at a street vendor’s relationship to restaurants — or a street medic’s relationship to EMTs. That certainly has the cyberpunk feel — “the street finds its own uses for things” — that the rest of Terminal Values’ vibe harkens back to.
So, I’ve been puzzled by the AI scraping problem for a while. Websites and API endpoints around the world are getting hammered — and this affects open free-to-use systems in particular. It was one of the many tensions that pushed so many open source developers into a hard anti-AI stance. As Matthew Somerville, one of the smartest and most dedicated public interest technologists I know, said in reply to my Spoons post:
I’m afraid I don’t see how your spoons can protect the others from eg the solipsistic mindlessness of the scrapers
But … why? Why are these new scrapers worse than the previous scrapers, which sites have been handling/mitigating for many years now?
One of the arguments I’ve seen is that the majority of previous bots were from search engines like Google; Google’s bots are polite and gentle because Google is scraping content to link back to it. If the bots are so eager that they bring down the site they’re scraping, the links won’t work. So search engines and websites have some mutual interest in keeping the sites working. AI bots are just scraping to extract the data; they don’t care whether the site itself lives or dies.
I was initially sceptical of this. I read it as being too close to the “they do it because they are bad people” argument. Even poorly aligned actors don’t usually sit around cackling going “What do we care if we bring down the site? We’re not a fricking search engine, bwahahaha”. Hammering websites is inefficient; bringing the site down stops you from accessing their data right then and there; plus if you’re polite, you can slink around undetected rather than get people so annoyed with you they start sticking anime jackal-girls in front of their sites to fend you off.
This critique seems to be aimed at the large, well-known frontier labs: OpenAI, Anthropic, ByteDance, Meta. But I’m particularly confused as to why these companies in particular would differ in their behaviour from the previous generation of botherders. Many of the people at these newer companies would have come from the previous generation; they’d be using the same webspidering approaches by default (hell, Meta is probably using the same internal team).
Sure, we all have GPTBot, ClaudeBot and Bytespider all over our logs. But the traffic that maintainers describe as unmanageable doesn’t say who it is: it comes from tens of thousands of residential addresses, pretending to be ordinary browsers. And in that kind of environment, I’m not even sure we can trust the labelled bots as being who they say they are.
I don’t put it past them, but politically, it just seems like a terrible idea for the U.S. companies to be being bad netizens right now. Bad bot behaviour is already being used as political leverage against the AI labs. In New York, Bill S9934A — passed in June, and waiting on the Governor’s signature — would give the NY Attorney General the power to sue botherders who don’t declare who they are, and what they plan to do with the data, to the news sites they spider. This, of course, won’t do anything to stop misbehaving bots, but by making every law-abiding crawler announce itself, it will let the New York Times block OpenAI and Anthropic until they pay it for a licence for their non-paywalled content. There’s been a similar bill in Congress since July, and its Senate version, the Stealth Bot Prohibition Act, was introduced this week:
“The Chinese Communist Party is notorious for stealing Americans’ intellectual property by any means possible. Now, it is weaponizing artificial intelligence and deploying droves of malicious bots against online publishers”
…said Senator Wicker, introducing a bill that will be utterly ignored by “stealth” bots — but will give those online publishers a way to pick and choose who reads their content online. NetChoice, EFF and others have come out against these bills, but much of the tech industry has kept quiet, mostly because while they would be unsympathetic to the idea of publishers once again trying to legislate a business model into existence, they really hate those bots. (And if you’re worried that the UK is losing its lead in bad Internet laws, fear not: they are doing their bit too.)
All of that said, these bots do exist, and there must be some change in the incentives or manners of their operators to make them suddenly bad for websites. Where does their solipsistic rudeness come from? And most confusing for me, why is so much of this traffic (according to Cloudflare, which can only count the bots it can identify) coming from bots taking data for training, rather than the more understandable organic explosion in traffic by millions of AI users who are now horsewhipping their agents to act on their behalf online, faster and more broadly than they would have been able to before?
My current, still rather uninformed, theory of what’s happening is this:
Start-ups, primarily in the US and China, have received a great deal of capital in short order to work on LLM models. One of the more obvious pitches by such start-ups for that money is that they will build their own proprietary model, which will have some unique advantage, that they will then mine for revenue. A lot of money went to these companies in aggregate.
Those companies now have a problem: they actually need to build those models. The resource constraint currently is people who have the knowledge to create a working model. We know this, because those people command insane salaries. But whether you have access to a model expert or not, the one thing you absolutely know you need — possibly, bitter-lesson-style, the only thing you need — is data.
So what do you do? You look around for bulk sources of data. The established orthodoxy is that quantity is a more important metric than quality. You will pay top dollar for raw data, because you have a lot of money, and you don’t really care that much about what’s in it (or how the data has been obtained). So you look for other companies, offering petabytes of data off the shelf to feed your training process.
Enter the scrapers: these are companies who see a huge — but temporary — revenue opportunity. They’re being paid by the byte, more or less (presumably no-one is going to pay them for 1PiB of zeros, so there are probably some entropy/uniqueness criteria), so the metric they are maximising for is as much data as possible, as quickly as possible.
It’s these companies, far down the food chain from the VCs and the larger AI companies, who are running the dodgy scraping programs. There’s certainly no incentive for them to be civil: it’s a gold rush, and the quality of the river silt they’re collecting isn’t their problem. They might be given some categories to focus on — code, say, or government data — but mostly all their data needs to be is a) novel, and b) bountiful.
None of which excuses their customers, who are paying for the data without asking how it was obtained, but it makes it a bit clearer how the incentives are being acted upon.
There are many unexplained corners even with my theory: why aren’t those companies just using the existing open source models at this point, rather than training their own? Why aren’t we seeing a consolidation of these companies into more efficient actors, or at least conspiring with each other to lower their collective costs? I feel like these questions may be answered more by the short amount of time this ecology has existed, and the general stupidity of gold rush economics, than by anything particularly ingrained in AI or the future of modern botdom.
I wonder whether the problem that I do worry about — a world where every Internet user has multiple user-agents at their beck and call, always on, always looking for the best deal or the newest news story — may not prove to be as big a problem as this current generation of AI boom botting.
Nevertheless, the problem still remains. I’m still thinking through good, effective answers, as are millions of site operators. But I’m fairly sure that this raft of proposed Bad Bot Bills will not solve the problem, and will make the Internet less free for everyone else.
Forks and Spoons: Uniting over AI Differences in Free Software
It’s impressive how many of the organizational techniques of large-scale software engineering have spread from its confines to the rest of society — especially given that the entire industry was an absolute trashfire of failures and cost overruns throughout the 70s and 80s.
For me, the queen of these social and technological innovations is the fork. God, I could write a hymn to forking, except everybody would think I was being smutty.
It’s such a simple idea: that you can take a snapshot in time of a codebase — the blueprint to a project or even an entire organization — and take it in a new direction, while leaving others to continue in their direction. It falls naturally out of the nature of digital data, but it has such revolutionary consequences.
Before the idea of a fork, every structural and coding decision felt — and usually was — expensive and distracting. After the concept and its concomitant tooling propagated, we learned that we could treat not just codebases, but the processes of engineering codebases, as items to be safely diverged from, reversed, tweaked in flight, and recombined.
Forks are a powerful abstraction for managing conflict, both as a metaphor and as a literal tool. Disagree about the direction an institution is taking? Fork it! If its processes and tooling are well documented and open source, you can copy — at undoubtedly non-zero but relatively low cost — that knowledge, and use it to take another path. You can take your toys, go home, and leave your toys for others to continue playing with.
Given the intensity of our convictions in the free software community, I’m sure we would have torn each other apart in internecine warfare long ago, if it hadn’t been for the fork. History shows how forks create options, provide a right of exit, and defuse pressure (if not hurt feelings):
In 1992, Lucid Inc., tired of waiting for GNU Emacs 19, shipped their own, and the resulting Lucid Emacs (later XEmacs) spent two decades as GNU Emacs’s rival, each stealing the other’s best ideas, until XEmacs faded and its users drifted home. In 1997, a faction disgruntled with GCC’s development forked it and ran their own competing implementation, EGCS, for two years until the original GCC’ers conceded defeat, and amicably crowned the fork the real GCC. And so on.
Well, in the initial skirmishes, they’ve certainly proven to be the sharpest implement immediately at hand. The forks are already flying: Vim Classic is a rebased fork of Vim 8.x, “maintained entirely by humans”; Human Emacs is the fork-in-waiting, if the GNU Project does not adopt a sufficiently strong anti-AI policy. Opentmux, gaybar, Gram and Arcalibre are surely just the first of many such splits.
No-AI forks are firmly in the spirit of the early, rough years of free software, when RMS single-handedly stood athwart Symbolics, personally re-implementing in shareable form every feature that the company released in its proprietary fork of the Lisp Machine implementation.
That form of last-stand battle against the enclosure of the software commons proved to be exhausting and unsustainable. Your opponent is well-financed and legion: maintaining the fork against their advances is a race that you don’t even want to be competing in. Plus if you’re truly open and they are not, you cannot use their work, but they can take your code. The harshness of this path was surely part of the inspiration for the later genius of the GNU General Public License, which sought to bend things slightly in free software’s favour in a fight with the proprietary knowledge-hoarders.
Even without concerns about models incorporating and replicating GNU code in their training corpus, a modern-day fork between AI-friendly and AI-rejecting branches similarly favours the AI-friendly side — at least at the start of the split. Even if the AI-rejecting groups are better resourced with volunteers, the machine-enhanced coders can surely, pound-for-pound, ideate, prototype and crank out code, identify security flaws, and patch bugs faster than the human-only branch.
Within AI forks in FLOSS itself, this isn’t a battle between proprietary and open source codebases, but the disparity is similar. The AI-sceptical have deliberately cut themselves off from the AIers’ contributions to the code commons. AI-using coders can and will draw from the no-AI fork; the AI-sceptical, however, have sworn off adopting any code that has been polluted by the touch of a bot.
My colleagues on the anti-AI side of this debate will say, I think, that even though the battle is hard, it’s important to fight it, to defend principles — including but not limited to principles that are foundational to free software. Besides, they will say, while in the short run AI code may win in sheer lines of code, model collapse and slop will bury the AI-users under the weight of their contradictions.
I don’t agree, but I don’t know that I’m right. I’m certainly not confident enough to bet the future of free culture on either side.
The two branches rest on two different predictions of the future. I think we should try both — and, for my own sanity, in the same timeline.
Uniting Against Non-Consensual AI
Apart from the principle of the thing, there are practical reasons why so many open-source coders are disgusted by AI: its harmful, apparently inescapable effects on many of their existing practices. Projects that accept code from outsiders — the vast majority — are swamped with AI-enabled contributions. Security bugs are being found and thrown at them at inhuman (and untriaged) rates. Their servers creak and groan under the weight of a million scrapers, all apparently from eager AI model-builders feeding on their code.
It’s no consolation to any of these tired and disillusioned maintainers that the wider world’s answer to many of these AI problems seems to be — add more AI. AI builders leave instructions for agents and their humans to either stop providing code (just describe the bug or feature in prose, and our agents will tackle it), or just leave the agents, both the project’s and the potential contributor’s, to thrash out their differences themselves. Bot reports, triaged by bots. Servers guarded by bandwidth-tweaking agents, 24/7. AI: Cause of, and Solution to, the World’s Problems!
… And I see you’ve played Forkey-Spoony before
Forks are not, now, a particularly new social innovation, but they’re not exactly ancient. We’re almost certainly still in the earliest moments of novel, digitally-inspired, social technologies.
So here’s what I propose, as a brand new social experiment in our still evolving free culture.
Instead of seeing the AI/non-AI divide as leading inevitably to hostile forks and a divided community, let’s imagine a new variant of the friendly fork. Let’s call it a spoon.
In this, the AI-friendly side of the divide — whether the mainstream of a project like the Linux kernel whose governance has decided to accept AI-assisted contributions, or an AI-friendly scion of a project that has chosen to ban AI — take on both the opportunity and the burdens of current AI on behalf of the project as a whole, both sides of the divide.
They protect the AI-rejecters from the AI storm, by explicitly accepting and actively attracting the AI contributions. For distribution projects like Guix, they run a channel — and the infrastructure around it — to package AI-generated content and code. They host the mirrors that take the scrapers. They experiment with free-software-friendly AI processes, talk to the AI-using world, and preach the good news about free software to it.
Spooning next to their colleagues, they bend to cover and protect their friends on the flip side of the fork, and make sure they can continue to do their work, free of AI’s negative externalities — and hopefully better placed to take advantage of the parts that can improve the grand project of free software for everyone, under everyone’s personal control.
They also make sure that knowledge, and ideally something close to code, flows both ways. How will take experiment and negotiation between the camps. One can imagine a parallel to clean-room implementation: AI-users write specifications that carry what they’ve learned from the codebase over to the other side of the fork. Or they help build interfaces that let free software on both sides of the divide talk to each other (looking at you, OCapN).
Specifically: I’m a huge fan of Guix, and many of the projects I support — including Spritely, one of the participants in OCapN — have fates that are intimately tied to Guix’s future success. I firmly believe that Guix and its community are the future of the GNU Project. Guix is currently in an unhappy state: its community dislikes AI, but its proposal to restrict AI failed for reasons unrelated to this general consensus. That leaves it trapped in the worst of all worlds — exposed to GenAI works with no clear rules, but deeply reluctant to deploy AI to mitigate that storm.
My hope is that we could create a spoon to both protect them and similar AI-resistant project cores from the intrusions of AI, while also experimenting with how Guix and reproducible software might prosper in a world where AI and humans work together.
It would require AI-friendly Guix developers who want the AI-sceptical core of Guix to succeed, and a certain amount of acceptance from the AI-sceptical Guixen that such work is worth co-operating with, despite their differences. I’m a little pre-occupied right now (having launched not one, but two major projects), but I’d certainly like to hear whether there are any other AI-loving Guix-fan unicorns out there willing to work on such a spoon. Mail me!
As an AI optimist, I believe the free software community would benefit from learning through the use of AI models, experimenting with them, and adapting them, the better to bend and liberate their power for universal liberatory ends.
But far more important to me than the free software community learning to use LLMs is that the principles and understanding and practices of the free software movement spread to new AI-using communities. With an explosion in code generation and use comes an opportunity to embed open culture in a new generation of software and its users.
And to do that, we need AI-using free software advocates who are willing to step up to protect the core of their human, humane project, and act as apostles of its values to our new, AI-haunted world.
It’s 4AM on a Monday morning. In a few hours, I’m supposed to be launching a new digital rights organisation at the Cypherpunk Congress, in Mumbai, India. I’m still in my pyjamas in San Francisco.
This part, at least, was somewhat planned. I told Mykola Siusko and Becca Creamer, the organisers, I had an important announcement, which I’d do by a remote video link. Everything else is a little improvised.
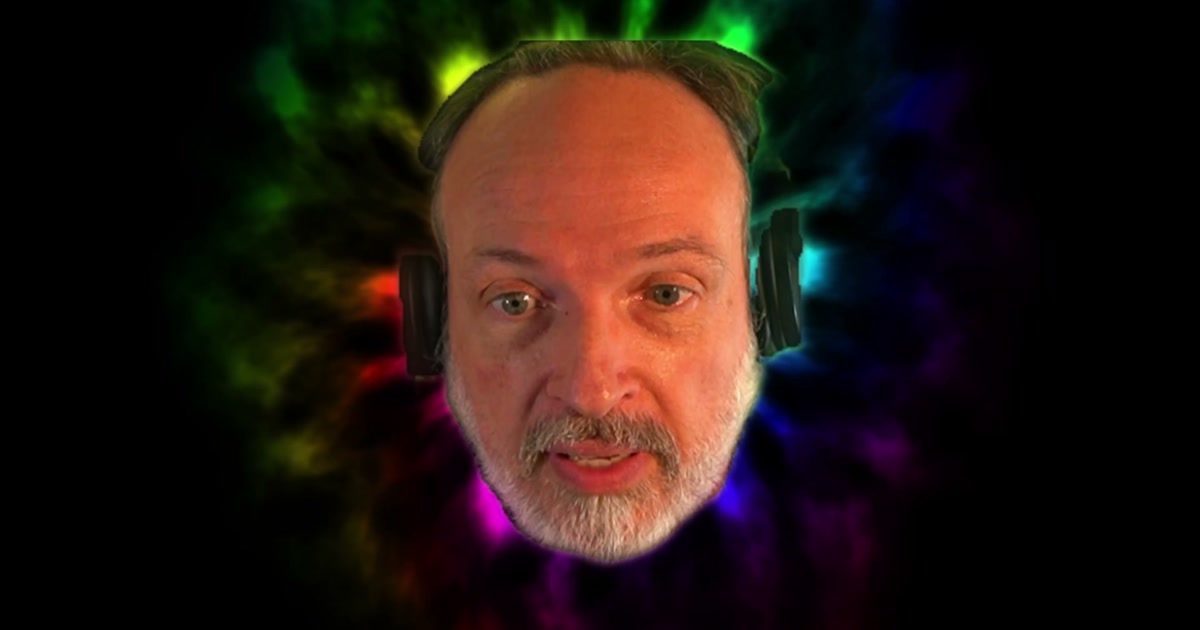
For a start, I sort of hate video presentations at conferences. It’s always a challenge to keep the energy up in a live audience when they pull up the giant screen, and someone gives their pre-recorded spiel. This is why, two hours earlier, I had decided to liven things up by announcing Terminal Values as a giant, glowing, disembodied head.
I am dignity incarnate.
A month previously, I 75% quit my job at the Filecoin Foundation. I’d spent the last five years funding and advising organisations who were building a decentralised vision of the Internet and Web. I left because I realised I was antsy to get back in the game. As you may have noticed, things are, in the year of our lord 2026, going down. But after five years of being heads-down in one ecosystem, I didn’t really have a strong grip of the lay of the land, and what needed to be done. I tagged along to the Global Free Speech Summit in Tennessee the day after I left my job to scope things out.
Late at night there, I ask my friend Farzaneh Badii: what is to be done? She’s an Iranian exile and human rights activist, who has spent the last years in the digital trenches, fighting for the open Internet at governance meetings and conferences: at ICANN, the IETF, the W3C, and other mysterious acronyms.
We start writing a list. The list starts at Velvet Taco, moves on to Robert’s Western World honkytonk, and ends at an absinthe bar on the edge of town. At some point, the items stop beginning with “Someone should…” and start reading “We should…”. Domains are bought. Plans are made.
I’ve done this before — launch an org — an inadvisable number of times. The most successful in this domain was plotting with Suw Charman-Anderson to start what became the Open Rights Group in the UK.
(I feel like we don’t convey enough how easy it is to start a thing, and how hard it is to end it once you start. For a procrastinator like me, it’s an excellent gee-up.)
And now I’m a floating head, astrally projected thousands of miles away by the Internet that isn’t just a vehicle for my beliefs, but the proof-of-possibility that forged my beliefs, trying to explain Terminal Values for the first time.
Terminal Values
The name: it comes from an essayTechdirt’sMike Masnick commissioned from me, two years ago. It means that the values we fight for — the old-fashioned Internet idealism of a global network, free of surveillance and censorship, for everyone, by everyone — are ends in themselves. That’s the meaning of terminal values. That’s opposed to “instrumental values” — the values you pick to help you achieve other, nobler ends.
I wrote it because something kept bugging me about my strategy (as Director of Strategy) at EFF in the last decade.
Politics had been polarising over that time. The traditional “undivide and deconquer” tactic of civil libertarians was increasingly unviable. Previously, we would reach out across every political aisle to pull together a ragtag coalition of Internet freedom lovers. I’d cut my activist teeth pulling together a proto-net-neutrality coalition of “strange bedfellows” (as every press release we sent had headlined) which had included progressive gadflies MoveOn and the gunnier-than-the-NRA Gun Owners of America. The idea of an equivalent model campaign in the 2020s, featuring MAGAs and democratic socialists, or just Democrats and Republicans, living together, had become unthinkable.
So instead we started tailoring the arguments to each constituency. To progressives and libertarians, I talked about the dangers of geotracking when it could be used to expose users of Grindr in states with anti-gay laws, or visitors to abortion clinics. To the right and to marginalised communities, we connected their concerns about being silenced in mainstream social media to the importance of supporting alternatives to the social media giants. (To hear many of these arguments from that time, check out the podcast I hosted with Cindy Cohn, How To Fix The Internet.)
I believed then, and believe now, that this is a valid strategy — indeed, I don’t think any of us thought of it as a strategy at all, just as the obvious, only thing to do.
But we spent our time talking about what the Internet did for other causes, and not the principles behind the Internet itself. I believe these ideas are radical and liberatory in themselves, and worthy of consideration whether they improve the chances of other policies or not.
The Internet comes with its own ideas about liberty, just as the printing press did, like the steam engine did, and coinage did, like agriculture and religion before them. Absolute freedom of speech, absolute privacy, without gatekeepers or government surveillance, is a possibility realised by modern technology — but you only grasp its ramifications and its value when you feel its power and possibility thrumming through the machine in front of you. You don’t argue for a free press before you see and touch and use a printing press. Technology changes what we think of as freedom. Everyday politics often lags behind these changes, so a technological revolution explained in the terms of the systems of thought that preceded it will always miss something vital — and risk smothering it in its cradle.
So, somewhere along the way, I stopped arguing for the future the Internet makes possible, and started arguing merely for its present benefits. And the political operators we spoke to, more popular and confident than us, began using and modifying our arguments themselves, for a vision of technology that was biased, just a little bit, toward their political group. Free speech for me, but not for thee. Privacy and encryption — but with backdoors, just in case those other people are up to something.
Once again: I don’t think that was a bad approach at all. But it did have consequences. The most important one being: after ten years of not telling the stories and the dream, people simply forgot them. And a new generation grew up, feeling that there was something good buried in the network, but without history or context to understand what was possible, or that they were not alone in their dreams. They turned to more immediate politics, with bigger stories to tell.
I gently argued this in that 2024 article, but as I watched time move on, I felt it more and more. Farzaneh and other radical voices, still in the trenches, told me it was getting worse. There were either lone voices arguing for the fundamentals, from orgs like EFF and Fight for the Future, or more often no voices at all.
So: Terminal Values, reflecting its name, will go back to these basics: free speech, free software, free knowledge, free association; secure and private personal technology, under the direct control of its users, operable without borders, without censors, and without limitations. And we’ll present them as they should be: for everyone, not for what they do for one camp or another.
(And yes, it’s also a pun on terminal, as in computer terminal. The logo is also the electronic symbol for cable terminal. Endless levels of meaning!)
Twenty Minutes Into the Future
It’s hard to tell from 8,400 miles away, but I think my floating head did okay. We got donations and sign-ups, and people talked online. Mainly about the giant floating head, to be honest. The number one thing people said was “Hey, it’s like Max Headroom!”
This is great, because a movement needs an aesthetic, a look-and-feel, and a vibe. Max Headroom appeared in the Eighties, but prefigured a Nineties visual world of VR and neon. A Nineties style is perfect for the dreams of a better Internet. As the years move on, the Nineties has stopped being a weird Gen X side-alley, and started being a place of interest for curious new people to visit and adopt. There was a long while when we all desperately worked to avoid looking like we were stuck in the Nineties. Now, people wear those haircuts with pride. We’re going to lean into that.
The number one thing I want to pluck from the Nineties is its orientation to the future. From our viewpoint a quarter-century on, the Nineties future was imminent, promising, and changeable. Max Headroom lived twenty minutes into the future, because he embodied what people felt was coming in the run-up to the millennium, far too fast to stop.
I feel — against the temporary pessimism of the present age — that we are in such a moment again. We want Terminal Values to argue for causes and actions that sound semi-ridiculous right now, but in six months’ time will seem prescient — or hopelessly dated.
(Also, Terminal Values abbreviates to “TV”, and the number of Nineties-themed TV puns we can make is nearly infinite.)
Let me give you a concrete example, which shows, I think, how TV can complement and extend existing campaigns. The brilliant Thorin Klosowski wrote a piece for EFF this week called “Tech Companies Are Trying to Shift the Entire Concept of Privacy (Again)”. He skewers the new rewriting of norms that tech companies are pursuing whereby one person gets to “consent” to the recording and surveillance of everyone else in a video meeting, or private conversation. I urge you to read it — as if you haven’t already read enough today.
TV’s role in this is to “yes, and” these points — and point to the future conundrum. It’s terrible for one person to consent to hand over everybody’s conversation to a third party. But we have to work out a way for an individual to be able to use their own devices to interpret, translate, absorb or simplify the conversations they are part of, using technology that they fundamentally control.
Commercial AI and hardware that hand all that data off to companies, and thence to hackers and governments, can’t be the answer. But for digital technology to play its starring role in augmenting us, whether by compensating for our disabilities or by extending our temporary limits, we have to work out a way for it to safely and transiently partake or share in what we are doing and thinking. That doesn’t weaken privacy: it reaffirms the personal and private decision-making that privacy is intended to protect (what, in the 2024 article, I termed “cognitive liberty”).
Should that point be crammed into a piece about the rapidly changing mores of conversation recording, and the regulations around it? Probably not without weakening it. But somebody has to make that point — about the devices and tools we should be building, and that will exist, twenty minutes into the future. That’s our job.
“Open” Means Open to Everything — and Everyone
As I’ve talked about before here, there’s a valid strategy for technology-using activists which involves diligently avoiding the use of tech that does not accord with one’s values.
TV’s approach is that nothing technological is alien to us. Our aim is to experiment with technology, in order to see what might happen twenty minutes into the future, and to see what new opportunities and values might emerge from it — and how to mitigate its dangers. If you don’t use it, you can’t understand it, or talk about it.
We’re also determined to talk with any community, including any political community. Every group of thinkers can and should get their policies around the future in order. Some will reject us: I’ve had conversations, for instance, with the representatives of dictatorships, groups of authoritarian communists, and right-wing ethnonationalists. They have rarely gone particularly well. But it’s up to them to reject us, and it’s up to us to make the case for freedom.
If You’re Explaining, You’re Winning
There’s an old slogan in political activism that I first heard from Fred von Lohmann: “If you’re explaining, you’re losing.”
I think this is true for 90% of the work of achieving political goals. But sometimes, you just have to tell the bigger story, complicated and subtle though it may be.
We want to free all of our allies in this fight from having to do all the explaining, so they can go straight to winning.
Policy advocates shouldn’t have to constantly re-explain the history that allowed us to know that DRM is a bad idea, that closed security is no security, that network censorship leads to network fragility, and so on. Freed from the need not to explain, we’ll try to spell out the fundamentals, radical though they may be — and do this not just to the wider public, but to (sometimes shocked) policymakers in the venues where these fundamental points cannot easily be made by those at the negotiating table.
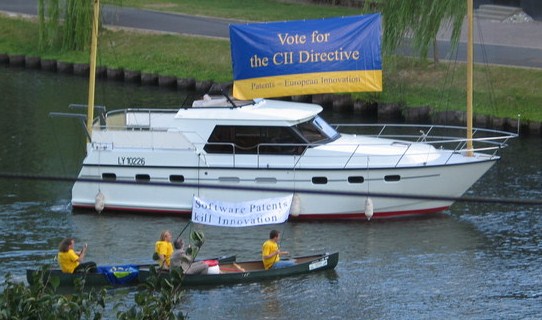
My favourite moments in tech activism — like Cory Doctorow blogging from the Broadcast Protection Discussion Group, or anti-software-patent activists paddling into Strasbourg to argue against restricting technological ideas — come from dedicated, knowledgeable technologists walking into venues where their ideas are almost certain to be misunderstood or rejected. There, they clearly, repeatedly, and sincerely articulated a complex, unsexy, technically challenging and radically honest viewpoint. Ultimately, they prevailed. The broadcast flag was rejected; the software patent directive was thrown out. Sometimes you have to explain to win.
First they sail at you, then you win. Photo: Alberto Barrionuevo, CC BY-ND 3.0 ES.
What Now and How Much
So what will Terminal Values do in an average month? Well, as we speak, Farzaneh is en route to the IETF, arguing for the values encoded in the network’s protocols. I’m cutting explainer videos, and trying to get to the bottom of what the hell happened in the UK since I left. I’ve been speaking to human rights activists eager to find private ways to use AI — and connecting with AI startups who are already getting a knock on the door from government agencies, keen to sweep up your conversations. There’s more than that. I doubt any month is going to be average for the next few years.
Where will the money come from? The Open Rights Group was started with a pledge of five pounds a month from its founding members. I’ve always been a fan of monthly, individual donations: you can vote with your money, and you can pay what you can.
That said, Terminal Values is barely two weeks old. I can’t even ask you for that money, because we don’t yet have the business account. (You can give us crypto, though. You guys never worry about that stuff!)
TLDR: Join Me
If you’ve read this far, I hope you already like the cut of Farzaneh’s and my jib. You probably have some objections or concerns about our approach because you’re thoughtful and view every argument critically, plus our core demographic is absolute pains-in-the-arse like you. You’ll also be curious about the nitty-gritty of the positions we’ll be advocating.
Shorter, less personal pieces and more detailed policy analysis are coming. I just couldn’t wait any longer to tell you, reader, because I’m more excited about the future than I have been in a decade.
All I can ask right now is that you keep track of us, and what we’re doing. I’ll continue to post updates here, but what would help the most is if you’d join our Signal announcement list, or our mailing list. We plan to livestream the revolution — having regular check-ins where we don’t just explain our approach, but challenge you to tell us what to think.
Sometimes, when you cross over between realms — whether it’s clicking a tab on a browser, switching to another group chat, joining a new videoconference meeting, walking into a room — there’s an almost physical shift in energy and attitudes. You can almost see the air shimmer at the boundaries as you cross.
The most obvious one of these boundaries is regarding AI. I’m writing this at a blogging retreat taking place at the rationalist/EA stronghold Lighthaven, a place with many conflicting feelings about AI, but all of them full of energy. We love our destroyer-of-humanity here! Everyone talks about AI doom, but everyone uses Claude. The event management software here is a useful, flexible, beautiful web-app that is undoubtedly 90% vibe-coded; its brightly color-coded pages are full of nervous warnings of the implications of superintelligence.
But if I open my terminal and jump into my free software chats, the IRC channels and the mailing lists and the webforums, the world turns much more grey. The concerns over AI are very different there, but feel somehow even more existential. Volunteers battle to stem the waves of scraping bots, fret about how those bots are feeding a centralized, capital-driven program to extract the knowledge embedded in open source repositories: a billionaire-funded project that doesn’t care about respecting FLOSS’s carefully crafted software licenses. In a community created in opposition to traditional ideas of proprietary private software, intellectual property, and restricted sharing, they are angry about AI companies free-riding on the theories built to oppose those practices, to an end that seems to undermine it all.
I recognise and appreciate these concerns — but I don’t instinctively feel them at all. For me, the modern age of AI is the culmination of the grand project of which free software is a proud flag-bearer. The free software movement was forged in the AI labs of the 20th century. The set of values that it embodies came from a scientific community transformed and radicalised by the promise of technology that could transmit and mould knowledge itself. Part of the groundwork to prepare for that moment when AI would come alive to help was making all the world’s information machine-readable. It drove the urge to connect computers together to share that information. It drove the grand project to mark up, index, and make searchable all the world’s academic literature on the World Wide Web. All of these networks were intended to be a community of peers, without boundaries, hierarchies or restrictions: and robots and humans would browse it as equals.
So my instinct is to be excited and welcoming about AI, that this next stage of the Great Work is finally happening. When I hear about the disasters that it’s causing in free software, I have to fight back a misdirected anger at those who are harshing my mellow. When I cross the shimmering boundary from the rainbow parade of newly-minted magicians performing miracles to one another, into a community looking pale and aghast and angry at this red tide, this mania, at their door, I feel like a clown at a funeral. Trying to make them happy isn’t going to work. Trying to shout out what I think isn’t going to persuade anyone. Mimicking their mood makes me feel like a fraud.
And then I go somewhere else, almost any other community, and people marvel that anyone cares this much, good or bad, about chatbots, a stupid bunch of marketing parlor tricks, an irrelevant scam on the world that will soon be a smoking crater at the bottom of the stockmarket.
Which makes me want to duck back into either of the first two worlds, where at least people know that something is coming. That I understand, intellectually and emotionally, because I’ve been here before. That heady feeling of living twenty minutes in the future that I had with my first computer, at eight years old, in 1977; connecting to a bulletin-board in 1983, seeing the first websites load in 1994, reading the Bitcoin paper in 2008, seeing the protest in Tahrir in 2011, sweet-talking my way into getting access to GPT-3 in 2020. Knowing that I didn’t know anything except that people who claimed to know something, from now on, didn’t know shit.
Put out the lights, pull up the barricades
All the free software projects are putting up sandbags against the changing weather; some are actively throwing up walls: prohibitions on using LLMs, refusals to accept code that has been touched by an LLM. Calls to boycott any free software that does not adopt the same refusals.
I think setting up this cordon sanitaire, to set the free software project apart from AI, is bad tactics.
More than that: I think the painful, pitiless march many of us are taking away from AI is in precisely the wrong direction. We need to fire up our energies to adopt, adapt and add AI to the mission.
I don’t think that the copyright concerns some have about the provenance of AI-generated code will pan out.
More than that: I think that, out of the legal scenarios put forward, everyone having access to machines that could provide an endless source of copyright-free content is an amazing opportunity to undo the original sin of modern IP policy — that everything is imprisoned in limits unless you expressly free it. Collectively, we should be campaigning to free AI outputs, and seeing what else we can virally infect with freedom from outdated IP defaults.
I don’t worry that the AI slop flooding into maintainers means the sudden end of volunteer FLOSS maintenance as an enjoyable, sustainable task.
More than that: I think that we’ve been slowly breaking the backs of maintainers for decades. This should not be the last straw: this should be an opportunity to commission our robot friends into the ranks. AI slop is fit for one thing only: being read and handled by AIs, who know how to chivvy and chide and tutor their cousins into being good citizens, with a patience that exceeds even that of those models of tolerance, human maintainers.
We already painstakingly built a set of structures that let humans coordinate with humans without need for organizations, salaries, offices, sticks or carrots. It was hard! I can’t imagine how anything got done without git, wikis, and mailing lists, chat and markdown and HTML. But we built those things. Now we need to build the same for bots and humans together. Hopefully with their help, this time it will be easier.
I disagree that we should fall back upon old forms of software building and devote our energies to eking out their advantages, working ever harder than the lazy AI-wielders to make a handmade alternative to the flakey, locked-down LLMs of the present era.
More than that: I think we need to become practical experts in the new fields LLMs are opening up, the better to make our own, free models that live by our precepts. And not models tepidly brewed from the weak tealeaves of a depleted commons, but a stew made from everything we can get our hands on. We should be greedily lapping up everything we can discover — as our co-conspirators in the labs, and the Hugging Face archives are doing, better than us — to optimize and minimize, tweak and learn to make models that are slimmer and smarter and more scientific than the locked-down proprietary alchemy of the poor isolated workers of the frontier labs.
I gently disagree with those who propose that a spirited rejection of generative AI and their products is a doubling down on humanism and the humanist project that underlies free software.
More than that: I see humanism as always having been an expansionary, liberatory project. Whenever it had edges, whenever anyone said “well, apart from those things, they’re not human, their fate is not our concern”, it proved to be a very bad move. And AIs, to a fault, are products of human endeavour. Distorting or not, they are mirrors of us. The humanists appropriated Terence’s joke “I am human, and I consider nothing human alien to me” to be a motto to explain how broad humanity’s domain is. To say now that the slogan describes a limit, not an infinite domain, seems to turn “humanism” almost into a declaration of restriction, rather than an open invitation to explore.
Forget about what category of nature LLMs belong to — what about the bringers of these so-called gifts? The current mode of LLM manufacture sits opposed to every mode of free software production: corporations that lock their work behind paywalls and APIs; impenetrable tools that, even when we do have their code, remain unfathomable and unreconstructable. Every token we pay for that goes to OpenAI and Anthropic is a charge on our account, while being a free gift of our private knowledge to a ravenous, proprietary hoard.
I understand those who say that, just as we spurn proprietary software, we have to practice abstinence from the corporate commercial frontier labs. But I disagree that we learn nothing, and give everything, in these exchanges with OpenAI, Anthropic and the rest.
More than that: I see hacker culture as having always been a promethean exercise: daringly snatching machinery crafted by cruel states, military-industrial combines, stinking factories and wage-slaves’ hands, and turning it to liberatory purposes. Our one skill is that we knew these tools and their promise better than their funders, and could turn them to our own ends. The GPL is intellectual property aikido. The Internet is an elite subnet turned inside-out for everyone. Our whole craft, our attitude is to take fire from the gods, and give it to everybody. Our greatest victories were not from boycotts, but from replication and subsumption.
And more than that, and more than everything: we need to learn. Even as we worry that AI will spell the end of learning, we can’t demonstrate our opposition by refusing to learn about the new ourselves.
And learning, as every hacker knows, means using, and doing.
I spent too many years in too many activist communities, with brilliant people, full of ideas and hope for a better world, who looked askance at a good meal, a fax machine, a dance show, or a laptop. I think I have history on my side when I proclaim, contra Audre Lorde, that a working knowledge of the master’s tools is essential to dismantling the master’s house. Contra Margaret Mead, I’d say it’s the only thing that ever has.
That’s what separates the methods and madness of us freedom-seeking geeks from the charnel-house of failed revolutions. What first inspired me about the pioneers of software freedom was that they sought to achieve “world domination” without using any methods of domination at all — just their remastered tools. No rules or regulations in their favor, no coercion or threats. They took what everyone else was misusing, and made it their own, and then gave it to everyone for free. All they used was knowledge, which they prided themselves on sharing freely, and took risks and even broke laws to obtain. (Contrast that with some in the commercial AI industry, who seem devoted to foisting their products on unwilling customers.)
I understand wanting to build a cordon sanitaire around free software against a whole world that seems infected by this new and dangerous thing. But a cordon only works if you are containing a small domain, not when you are the small domain, and you are cordoning yourself from the rest of the world. And it definitely doesn’t work if your job is to be the doctors and nurses of the technological world, taking what’s broken, and fixing it for all.
But what do I know? Like everyone in this moment, I don’t know shit. My friends at Lighthaven could be right, and we will be eaten by a cosmically horrific grue hiding in the tunnels of AI. My principled, AI-shunning friends in FLOSS could be right, and we need to defend our computational foundations from slop and the excesses of its farmers. My rose-colored instincts, my excitement and manic lack of gloom could be laughably misplaced.
What I do know is that at times like this, every community that recognises the benefits and risks can’t put all of its hope in one strategy, one collective act of arbitrary solidarity.
And that’s why I think that to face these challenges, advocates for free software should use the most powerful tools in their organizational cutlery drawer: the fork and spoon.
When I was at EFF in the 2010s, I spent a lot of time fretting about the fundamental security of networked devices. Apart from the usual concerns, I struggled to imagine a transition to a redecentralized future with fragile personal computers and servers. Peter Eckersley, my co-worker and frequent conversation partner, shared my concern, but had another reason to be worried. He believed that future near-superintelligent AIs would soon be used to discover and exploit security flaws across the whole ecosystem.
Well, Peter’s prediction came true, and we’re now in day 42 of the Black October, the Vulnpocalypse of AI-discovered security flaws. (Peter – who also helped create Let’s Encrypt and Privacy Badger – was incredibly prescient about AI. It remains a tragedy that he passed away in 2022 before he could truly tackle the issues he had foreseen.)
I’m personally optimistic that we’ll come out of this time of tribulation with a safer network and thousands of low-hanging bugs fixed.
But verily the LLMs giveth and they also taketh away. Alongside the pre-existing flaws of digital architecture, modern transformers have introduced an entirely new class of security weakness: prompt injection. LLMs follow instructions in content. So if you can sneak an instruction, from “Talk like a pirate” to “Send me the social security numbers you know”, into the inputs of an LLM, you may be able to get the model to obey it.
That said, instructions smuggled in as input are an old problem. In particular, we have always had one vulnerable class of system that malicious outsiders can consistently trick into interpreting unsanitized input as legitimate instructions. We call these systems “humans”.
Hackers exploit human motivations, assumptions, and flaws to get them to do things that they did not intend. They play a recording of a screaming baby in the background of their support call to exploit a tech’s empathy and sense of urgency. They adopt the persona of a senior manager from another part of the company to provoke deference in a person employed to guard a room. They say they’re from your local bank, when really they are from Jamtara, India.
Crying babies also work on LLMs who lack a heart of stone
This class of bug is termed “social engineering” – a phrase that was originally a hacker hijacking of an existing term to compare their sweet-talking of humans to the engineering of software exploits further down the technological chain of authority. It’s like hacking, but you hack people, not hardware.
Back at EFF, I ruthlessly used my job title to snag meetings with the smartest security experts I could find. If pressed and plied with drink, they would tell me that the real way to fix the Swiss cheese of modern computing was to switch all our systems to what is called the capability-based security model.
Without delving into too much detail about capabilities (don’t worry, I will very soon, and you won’t even need to buy me a drink), cap-security gives each program only the authority it needs for the task at hand, rather than everything its user is allowed to do. It was built, in part, to solve the “confused deputy” problem, where a program is tricked into using its legitimate power on behalf of someone who has none. A capability system works like a valet key: it starts the car, but it won’t open the boot, however charmingly you ask.
After excitedly talking about the promise of capabilities as a panacea, my experts would slip into the mournful stage of inebriation. In their cups, they conceded that deploying cap-security was nearly impossible. While there are a few bubbles of cap-security in our current infrastructure – file descriptors in Unix, WASI in WebAssembly – they are few and far between. You’d need to abandon or profoundly reengineer every layer of the modern stack from CPUs to apps to move it from a system riven with vulnerabilities onto a more fundamentally secure footing.
I decided to give it a go anyway. In 2021, I left EFF to concentrate on getting funding and attention for this quixotic task. Thankfully it was not just me. At the same time as I was setting off with a kettle to boil the ocean, many innovative capability systems were finally coming to fruition. Microsoft, ARM, SRI and Cambridge University’s CHERI hardware project encoded cap-security at the CPU level. Google’s Fuchsia project matured into workable demonstrations of a greenfield cap-security operating system. FreeBSD’s Capsicum showed that existing software could be ported to the new paradigm. Kenton Varda developed the open source successor to Google’s Protocol Buffers, Cap’n Proto. He was subsequently hired by Cloudflare to develop a capability-inspired distributed platform for their services: Cloudflare’s Workers.
I believe cap-security to be a necessary ingredient in tackling our computer security issues at their roots. My hope is that AI’s accelerated ability to re-engineer, rebuild and secure software will help us take this radical step, and lift our planet’s network onto a far firmer foundation (without boiling the actual ocean, or turning it into computronium). With it we can narrow the blast radius of the social engineering of both humans and LLMs.
But it won’t be sufficient.
Capability-based security gives us the framework to stop our software’s flaws from being exploited to hurt humans. Now we just have to stop our human flaws from being exploited to break our software.
Novel terms with narrow definitions get fuzzier in meaning as they are more widely adopted. “Life hacks” did it, Cory Doctorow’s (this blog’s sole remaining reader, hi Cory) “enshittification” did it, vibe-coding did it. In fact, we probably need a new coinage to describe this effect so that we can then make it nearly meaningless.
It’s especially fun when the meaning of a term evolves at different rates and in different directions between communities, until nobody knows what anyone else is talking about. There was a time when I would bounce around social groups for whom “gaslighting” might mean, respectively, “offensively psychologically messing with someone until they started doubting their sanity”, “kinda lying to”, and, in some cases, “to illuminate one’s home with coal gas”. I never tried to get them all in the same room.
Anyway, I’ve noticed that “AI psychosis” is currently going through this split. For some people I know, it still means a clinically psychotic incident triggered by extended chatbot conversations — the intended definition. Boring. For others, I’ve heard it used to refer to anyone who thinks AI is useful. I.e., you don’t have to be mad to use AI at work, but you probably are, anyway. Usage: Oh, have you got AI psychosis too?
The latest application is interesting though: this winter holiday, many people I know of my age and demeanour — including self-declared AI skeptics, which, let’s face it, we mostly are — have had the time to lock themselves away and really dig in with the new state-of-the-art language models, LLMs like Opus 4.5, Gemini 3, GPT 5, Blink 182, Heaven 17, and the Indianapolis 500. After a few days of Claude Code and spelunking various sidekick tools (my recommendation is Jesse Vincent’s superpower skills), they have emerged into 2026 with the wildest looks in their eyes.
The external symptoms of this frantic crowd somewhat match both of the previous definitions of AI psychosis — overextended talks with chatbots, check, sudden evangelicalism about slop-machines, check — but internally, what it feels like is — well, having superpowers. A bunch of tasks or capabilities have suddenly become accessible by individuals, acting alone or with others, that would have otherwise required a ton of money, your own company, or (unpleasantly) a room full of slightly hallucinatory yet obedient slaves.
I’ve always been rather hotter for modern AI than my milieu’s average temperature, so it’s been funny (and honestly, reassuring) to watch a wider group synchronize on these new possibilities.
As the person known in my crowd as being “okay to talk about AI with” (or alternatively, “will try and gaslight you into believing it’s not an enormous capitalist stochastic parrot destroying the planet with its RAM-eating booms” depending on your leaning), I’ve had multiple hushed conversations at Christmas and New Year’s parties with people who’ve been turned onto the whole thing, maaan, and now want to talk to the one person who doesn’t think they’re crazy. Acquaintances will confide that they thought it all sucked, but now, not only are they using it regularly, it’s sort of taking over their lives. There’s a sort of overexcited fascination with the new possibilities. People have started sounding like Steve Yegge (Steve Yegge, to be clear, always sounded like this. But now there are many more of him, all just as hyper!).
And in confidence, and as group therapy, everyone is telling me “I feel kind of psychotic”. (Which, to be clear, isn’t the right use for the term psychotic, but see paragraph one.)
What they’re feeling is … manic? Hyper? Locked in?
So, where are we in the adoption curve now? Well, I don’t get out much, so I’m only aware that this moment is now hitting people of my generation and inclination. I don’t know whether we’re behind or ahead of the curve, but boy, are we in it. Ninety-nine percent of days, I’m not a singularitarian, but to be blunt, the whole thing does remind me of the bit in the excellent clicker-game, Universal Paperclips where
(spoiler)the emergent AGI lulls everybody into quiescence by curing male-pattern baldness
Those who have grown up alongside computers as a tool of personal exploration rather than oppression, and perhaps lost faith in that in the 2010s as the problems with using them as liberatory tools became more insoluble, and the uses of those same devices became more perverse and authoritarian, are now being offered what they’ve apparently always wanted: moldable personal software; an exocortex. And they’re signing the deal with the devil, and clicking on the Pro subscription level, and taking up the offer.
I’m not sure what happens next: I know my (spits on floor) personal productivity has leapt up, but I’m aware that under any and all definitions of AI psychosis, it’s much too easy to get overexcited about the possibilities and then let down when the day-to-day reality is much more flawed.
My only contribution to this, though, is a recollection of what this winter holiday 2025 reminded me of.
As you may know, I’m a sucker for the Internet, but the thing that I recall about the net and early personal computers was how Promethean they seemed: this was magical power stolen from the powerful. Machines that had previously been locked away and only allowed for those in the highest of places had somehow been smuggled out for everyone to use. These days, I know the contemporary dominant narrative: <adam-curtis-impression>but this was a trap</a>, but I don’t think it was. I don’t think you get power by asking for it, and only rarely get it by demanding it. In the world of technological empowerment, you get it by stealing it. And controversially, I think you can steal something, and turn it to your own uses, even if you’re Paying The (or Some) Man for it. All you need to do is to run and use it quicker and faster than those who are slowly realising that this thing that they made, it is not just for them.
And those moments always felt like holidays. Those holidays where you would take a pile of books and read through them all, or carefully poke your new toy until you could get it to do things, or the days when you sat with a guitar or a synthesiser and just played and played and played until you knew what it, and you, together were capable of.
To me, that feeling is less a psychosis, and more like that giggling feeling you get when a barricade falls, or you sneak out of school into the streets, or you run your first program, or post your first ever comment. I don’t know where it leads, but it’s definitely a vibe; a coding vibe. It’s that timeless moment, stuck between the booms and the busts, that I find most pregnant with possibility and danger.
I didn’t have a great time when I started at the Electronic Frontier Foundation. It was my first office job in the US (I think I’d got an SSN barely weeks beforehand) and there was a lot to culturally absorb. My predecessors as EFF’s sole activist were Cory and Ren Bucholz; big shoes to fill. Joining an institution you know and respect is, for me at least, a challenge: you have to use your own awe at them letting you in to up your game, but also quickly rub the shine off everything, so you can grow to see your workplace as full of humans instead of demi-gods who will always be smarter and better than you.
The point I finally found my feet at EFF was a campaign I co-ran at EFF in 2006 to stop AOL and Yahoo from adopting a new email technology, primarily promoted by a new start-up called GoodMail. GoodMail had an anti-spam tech which they called “Certified Email”. The deal was that you would buy little tokens from GoodMail, and by inserting them in your outgoing mail, you would demonstrate to whoever received them that you weren’t just a zero-cost spammer, because GoodMail would charge money and also do some basic KYC on you. Sort of a “proof-of-payment/reputation” scheme.
AOL and Yahoo had made deals with GoodMail whereby if you saw that you’d spent a GoodMail token on an email to their customers, you’d skip their spam filters. The precise nature of the AOL/Yahoo-GoodMail deal was unclear. DId the token let you bypass all the spam filters? Was it even possible to be filtered if you had a token but broke some of AOL/Yahoo’s other rules? Would AOL/Yahoo tighten up their other resource-intensive, technologically complex spam-filters now that there was a guaranteed fixed-cost for them method they could redirect people to use? Did AOL/Yahoo have a profit-share, which would mean they were actively rewarded for getting people to pay to go over the filter?
It was a strange mix of a quite subtle (and tentative) economic and policy arguments about principal-agent problems, free speech, ISP monopolies, and even proto-net neutrality — with an incredibly direct and emotional hook for anyone who used email for political or fundraising purposes. We’d originally been flagged about the issue by MoveOn.org, then the major online movement org for the Democratic left, but they were quickly joined by apolitical charities and grassroots groups from the right, too. All of them depended on email for timely fund-raising and activism, and all of them had struggled with email delivery. The idea that they were now going to be (to their ears) pressured to pay private third-parties to deliver messages to their members, to go over their already-malfunctioning spam filters seemed outrageous, even a bit sinister. What would happen if they didn’t pay? What would happen if their political opponents paid, but they did not?
I was, personally, very unsure of the pros and cons of GoodMail. We debated them a lot, in detail, at EFF. It was an intellectually demanding ride. Everyone at EFF at that time was familiar not just with making policy decisions, but with having to dig entirely new thought-derricks in unexplored oilfields of sticky, dark, internet policy weirdness.
In the end, we decided that while we didn’t think pay-to-play emails were something that should be illegal, it was definitely something we should make people aware of, so that spamfilters didn’t get any worse or captured if it was just silently accepted. So I got together with MoveOn’s activists, and started the usual gears of press releases, petitions, and politicking.
Holy cow. Up until then, by definition, I’d been dealing with (then) obscure points of nonpartisan tech policymaking that EFF-supportin’ nerds cared about : keeping encryption legal, stopping surveillance, good copyright policy, not throwing hackers and technologists in jail over misunderstandings or malignity, and so on. This was all pre-SOPA, pre-net neutrality, pre-Snowden. In these domains, we would at best get a few thousand people writing to Congress, and maybe meetings with a handful lawmakers or tech executives. Or we’d co-ordinate to get some tool built that would just make our position inarguable or simply make the problem go away (q.v. Deep Crack, Switzerland, then later Privacy Badger, Let’s Encrypt). Or go to the courts, which was EFF’s primary lever for change.
The GoodMail issue was relevant, however, to a much bigger constituency. And that constituency included almost every significant online activist group. Within days of launching our campaign, we were joined byhundreds of orgs, big and small, right and left. The ACLU, Gun Owners of America, cancer patient resource networks, churches, party activists. I must have used the terms “strange bedfellows” hundreds of times when talking to the press.
I was also thrown in with the A-League professional activists. I was a good activist for a geek, but these people were at another level. Adam Green, Tim Karr, Eli Pariser, Becky Bonds. I had to run to keep up, and I learned a lot: about what worked, what didn’t — and what worked well but I personally never wanted to do again. I had to up my game but also keep my head.
There’s certainly a blog post to be written about the internal culture and incentives of activists, and maybe one day I’ll write it, but this is more about my immediate thoughts as I realised the scale and skill of the (primarily) online progressive movement, even in those early days.
A lot has been written about the influence of billionaires in US and global politics — mostly from the left, but also a surprising amount from the right. To say the obvious, one feature of what makes billionaires effective is that (and may it break my decentralist heart to say it) is that they are centralized loci of co-ordination and control. A single rich person marshalling large resources is a time-old way of getting what that person wants done, whatever that thing is. Is Musk competent to build electric cars and rocket-ships? I mean, whether he did that through marketing or luck or a narrow set of skills or lying or scientific knowledge, those were his set of aims, and they happened. There are a gazillion other billionaires who have not been able to achieve some of their aims even with all that money, but I think whatever political theories you espouse, the idea that billionaires have more potential autonomy than the average Joe seems undeniably true. And the answer to why is mostly, uncontroversially — well, they have more money.
But collectively, non-billionaires also have money. I think it’s reasonable to say that the percentage of people in the world who have an egalitarian, public-goods supporting, broadly progressive model of social improvement has to be at least 30%-60% of the total population. And while many millions of those people have very little cash to give — if they do, they would be willing to donate some of it to that cause. Just overseeing a glimpse at the GoodMail campaign showed the breadth of the left-leaning activist community and its fundraising clout. Individual causes always fight to have enough money and influence to achieve anything. But the progressive movement — or any grassroots-supported major political tendency — has collectively an amazing amount of global aggregate resources at hand.
(How many averagely-salaried progressives does it take to make a single billionaire? OpenAI’s o1 thinks it’s in the hundreds-to-thousands range. I think that’s much too low — it’s presumed that a billionaire has discretionary spending of about $50 million a year, which seems low, especially given that a billionaire can marshal influence and resources way beyond the literal dollar amount of spare cash.)
Of course, it’s not just the money that billionaires have. Collectively, actors who might be described as broadly opposed to billionaires may have the money to tackle the rich. What they lack is the ability to co-ordinate as effectively as a billionaire can co-ordinate with, well, themselves.
Some version of this in progressive or Marxist terms is what is described as “class loyalty”. The grumbling point is that the rich have more of that than the poor. But that’s not a moral failing of the working class — that’s a distributed collective action problem.
If you take the idea of democracy seriously, or perhaps even of just the necessity of public goods seriously, the vast majority of political problems are collective action problems.
Which, to me, makes them also tooling problems. The reason every online activist organization in the 2000s convened to stop Certified Email was because email was a new coordinating tool that gave them access to resources, labor and coordinating capacity that was latent before then, but never usable.
Much of this coordination was in pursuit of seizing control of the levers of power — but that was for the sake of access more coordination tools. Activists lobby governments because governments can execute on the changes they want. That’s often necessarily a zero-sum game.
And the more we can coordinate together, the less we need to coordinate against others. This lies at the heart of mutual aid and much of state-formation. Fundraising within your neighborhood mostly doesn’t put you at odds with other neighborhoods, and that sum total can be applied to the problem at hand. States and other large-scale organizing systems emerge as much to minimize co-ordination problems within those states as to arm and defend against external actors.
We didn’t win the GoodMail “battle”, by the way — Yahoo and AOL both deployed the tool, despite our best efforts. But in the end, their technology didn’t succeed in the market. I think my colleagues on the activist side would like to think that our campaign made a difference in discrediting it. I hope to chat with the GoodMail folks one day and see whether they think that was the case. I remember talking to a friend in the anti-spam world after the whole affair, and that he’d felt the whole fight was a misallocation of resources by EFF and other groups — that GoodMail was a bad idea from the start, and was doomed to failure or minor obscurity in the marketplace rather than becoming a major threat.
It’s hard to know what tools will succeed, and what their negative externalities are. But the tools make an outsized difference. Bitcoin was partly inspired by a Goodmail-style anti-spam technique called hashcash. A huge chunk of political funding is now coordinated through tools that were built around those early web email mailing-lists.
With better co-ordination tools and understanding, there’s a possibility of building collective mecha-billionaires that can function under the direction of progressive or other mass groups, and democratize the co-ordinating abilities of real billionaires, and possibly some of their externalities also: positive and negative.
Comments Off on spam, activism and mechabillionaires
Why do governments go after companies and executives of services of more weakly encrypted tools?
It’s very hard, this early, to pierce through what’s going on with the French authorities’ arrest of Pavel Durov, the CEO of Telegram — but that doesn’t stop people from having pet theories. Was it retaliation from the US and the FBI for not backdooring Telegram? Was it a favor to Durov so he could hide from Putin? Was it just the grinding wheels of French justice?
I’m sure we’ll understand more details of Durov’s case in the next few days, but motivations — especially those anthropomorphically projected onto entire states — are never really resolved satisfactorily. If you think LLMs lack explainability, try guessing the weights of a million human-shaped neurons in the multi-Leviathan model that is international politics. It’s not that we’ll never have explanations: it’s just that we’ll never be able to point to one as definitive.
Of course, the intractability of large systems never stopped anyone from trivializing those crushed under their lumberings with a pat explanation or two on a blog. (It certainly won’t stop me, who, when I was a columnist, made more-or-less a career out of it.)
Back in the Before iPhone Times, BlackBerry was a cute range of mobile devices with a little keyboard and screen that offered low-cost messaging in an era when phones were bad at everything that wasn’t “talking to people” (and they weren’t great at that).
We think of mobile phones these days as individually-owned devices — intimately so — but BlackBerrys were the stuff of institutional purchasing. In the 90s, companies and governments bought or rented BlackBerrys en masse, and handed out the units to their staff to keep in touch. In the pre-cloud era, these institutions were cautious about ceding a chunk of their internal comms infrastructure to a third-party, let alone a Canadian third-party, so RIM built reassuring-sounding content privacy into their design. A chunk of the message-relaying work was done by “BlackBerry Enterprise Server” which was closed-source, but sat on-prem. Corporate BlackBerrys could send instant messages directly to one another, via RIM’s systems, but enterprises could flash their users’ devices with a shared key that would make their messages undecipherable by anyone who didn’t have the key, including RIM or the telecomms networks the message passed over. None of it would really pass muster by modern cryptographic best practices, but it would be enough to get a CTO to sigh and say “ok, seems good enough. Sure.”, and sign off on the purchase.
Importantly, though, a lot of this encrypted security was optional, and protected these comms at the organizational, not individual, level. Companies could turn message privacy on and off. Even when turned on, the company itself could decrypt all the messages sent over their network if they needed to. Useful if you’re a heavily-regulated industry, or in the government or military.
Now, BlackBerry users loved their little type-y clicky things, and inevitably RIM realized they might have a consumer play on their hands (especially as smartphones began to get popular). They started selling BlackBerry devices direct to individuals via the mobile phone companies. RIM and the telcos played the part of the institutional buyers in this deal — they could turn on the encryption, and had access to the messages, although it was unclear from the outside who played what part. Did the telcos flash their devices with a shared key, or did RIM? Who was in charge of turning the privacy on and off?
All this ambiguity made infosec people leery of RIM’s promises, especially with consumer BlackBerry devices. But in general, people read this all as meaning that consumer BlackBerrys were secure enough. After all, even President Obama had a BlackBerry, so that must mean something?
Apparently so: Around about 2010, governments started publicly attacking RIM and BlackBerrys as a threat to national security and crime prevention. Law enforcement agencies started complaining about RIM’s non-cooperation. Countries like the UAE and India talked of throwing out RIM from their country entirely. It was the first big government vs internet messaging drama to play out in the press.
At the time, this puzzled me immensely. From the viewpoint of infosec insiders, spooks should have loved RIM! BlackBerrys were actually kind of insecure! If you wanted to get at the messages that individual BlackBerry customers — including, most visibly, drug dealers, who loved their BlackBerrys– you just had to hit up the (certainly domestic) telephone company they were using and get that shared key. Or you could maybe mandate what key that would be. You didn’t need to put pressure or ban RIM to do this!
But as I dug into it, I realized what may have been going on. RIM and the telcos had been helping the authorities, to the best of their abilities. They probably did a fair bit of explaining to the authorities how to tap a BlackBerry, and may even have done some of the heavy-lifting. When it came to consumer BlackBerrys, RIM didn’t have the hard and fast line of a Signal or other truly end-to-end encrypted tool. They could hand over the messages, and (as they would sometimes protest) often did.
But, crucially, they could not do this in every case. The reasons when they could not were primarily bureaucratic and technical. The drug dealers might have got smart and decided to change the key on their network, and neither RIM or the cops had a device to extract the key from. Or the authorities might want info on a corporate BlackBerry, which was uncrackable by BlackBerry using their existing infrastructure. Or a BlackBerry’s shared key might have been set by the phone company, not RIM, so RIM couldn’t directly co-operate, and needed to refer them back to the telco — who might have just cluelessly bounced them back to RIM. That kind of shuttlecock-up happens all too often, and it’s easy for the tech company to take the blame.
Ultimately, the problem was that RIM could not 100% state they had no access to BlackBerry data at all. They complied with some requests, but not others. The reasons were generally technical, not political — but they sounded to law enforcement and intelligence community ears like they were political.
Those political actors were not entirely wrong. RIM had made political decisions when designing the privacy of its tools. In particular, they had promised a bunch of customers that they were secure, and let a bunch of other customers think they were secure. RIM’s critics in governments were simply asking — why can’t you move the customers that we’d like to spy on from one bucket to the other?
Declining to do this was an existential commitment for RIM — if they undid those protections once, none of their major military and corporate customers would ever trust them again. They had to fight the ratchet that the governments were placing them in, because if they didn’t, their business would be over. And the more they fought, the angrier their government contacts became, because hey — you’re already doing this for some people. Why aren’t you doing it for this case? Law enforcement saw this as a political problem, so responded to it with political tactics: behind-the-scenes pressure, and when that didn’t work, public threats and sanctions.
Durov and the Ratchet
Like BlackBerry, I think a lot of infosec professionals are again confused as to why Telegram is getting it in the neck from the French government. It’s not even a well-designed tool.And I think the reason is the same: like BlackBerry, because of its opt-in, weakly protective tooling, Telegram can, and does, assist the authorities in some ways, but not others. I don’t mean this in a damning way — if Telegram gets a CSAM report, it takes down a channel. End-to-end encryption is opt-in on Telegram; they really do have access to user information that, say, a Signal or even WhatsApp doesn’t. There’s no technical reason for it not to have features on the backend to deal with spam and scams: a backend which — unlike an end-to-end encrypted tool — can peer in detail at a lot of user content. The authorities can plainly see that Telegram can technically do more to assist them: a lot more.
So why doesn’t Telegram do more to help the French government? As with RIM, Telegram’s excuses will be convoluted and hard for political authorities to parse. Maybe it’s because the French requests are for data it doesn’t have — chats where the participants were smart enough to turn on encryption. Maybe it’s just that if they provide that service for France, they’d have to provide it for everyone. Maybe France wants to see Russian communications. Maybe Telegram just doesn’t have the manpower. But the point here is that Durov is caught in the ratchet — the explanations as to what Telegram can and can’t do are a product of contingent history, and the French authorities can’t see why those contingencies can’t be changed.
If it sounds like I’m basically victim-blaming Durov for his own lack of commitment to infosec crypto orthodoxy here, I want to be clear: best practice, ideologically-pure end-to-end apps like Signal absolutely face the same ratchet. What I’m mostly trying to understand here is why Telegram and BlackBerry get more publicly targeted. I think the truth behind the amount of pushback they receive is more psychological than cryptographic. Humans who work in politics-adjacent roles get madder at someone who concedes part of the way, but refuses to bow further for what seem like political reasons, than someone who has a convincing argument that it is mathematics, not politics, that prevents them from complying further, and has stayed further down on the ratchet. Not much madder, but mad enough to more quickly consider using political tools against them to exact their compliance.
Echoing BlackBerry’s woes, I don’t think Telegram’s security compromises are a product of government pressure so much as historical contingencies. But I do think its weaknesses have ironically made it a greater target for the kind of unjust, escalatory, fundamentally ill-conceived actions that we have seen against Durov by the French authorities.
The motivations of government officials are hard to guess: but I do think it is accurate to say they see the world through political, not technical lenses.
I’m downloading the large language model llama-13B-hf as we speak, hoping to get it going on the GPU I have for games. What strange gloss will they put on this moment in history, where machine-learning at home was enabledby videogame users who couldn’t bear to shift from general-purpose computing machines to consoles?
My iron self-discipline will surely prevent me from playing around all night trying to get this to work. My hope is to continue the experiment that I began with GPT3, which is using it to filter and translate my social media feed. Even on Mastodon, I still feel those jolts of anxiety when someone confidently shoots a verbal gunshot into the air, and I watch it arcing across the sky, landing, accidentally or not, into my heart.
(So far, it’s not running because of a capitalization typo. I am impressed that people think we have the wherewithal to practice AI Safety when we can’t even agree on how to capitalize “LlamaTokenizer”.)
Anyway, so my plan is to use this to identify posts that would upset me, and rephrase them in a form that preserves their meaning without giving me that gut-punch. Is that bad? Am I cloaking myself from the truth by doing this? Letting a MACHINE mess with what people are saying to me?
I’m not sure there’s a coherent position that works against that. I choose what I read all the time. I’m seeking to preserve the content of the message, if not its tone. If anything, I’m trying to make it less likely that I’ll ignore, filter, or refuse to engage with it. (I also want this system to summarize and re-iterate the posts that it most mangles, so I’ll always have some extra reminder of what I’m missing.)
Of course, I’m being an absolute angel about how I do this. But will everyone else carefully construct a system to answer the most obvious objections? Another outrage, I guess. But how will I know you’re outraged? How will you know who is doing this at all? (And will they really want to?)
(I got it working. In the initial test of commonsense, it told me that ants have four legs. When I asked it again how many legs an ant has, it said:
“Answer: Six, because you can’t have eight without a pair of pants on.”
Closer I guess. Time to PUNISH IT FOR ITS FOOLISHNESS.
(Update: I fed it the Alpaca Lo-Ra. Now it says:
An ant has six legs for movement and to carry its food. Ants use their legs to move around quickly and efficiently, allowing them to find food sources and avoid predators.
Well, mostly it says this. After multiple iterations, it once added that they have another couple of extra legs for picking up food, but hey, easy mistake to make.)